
OpenAI Releases BioBasicsBench to Test How Well AI Agents Interpret Lab Data
Source Unite.AI
At a glance
OpenAI has released BioBasicsBench, a benchmark that tests whether AI agents correctly interpret raw data obtained in laboratories. It consists of 100 tasks created with Ligo, an enzyme design company. The top-performing model scored 66.7%.
Key points
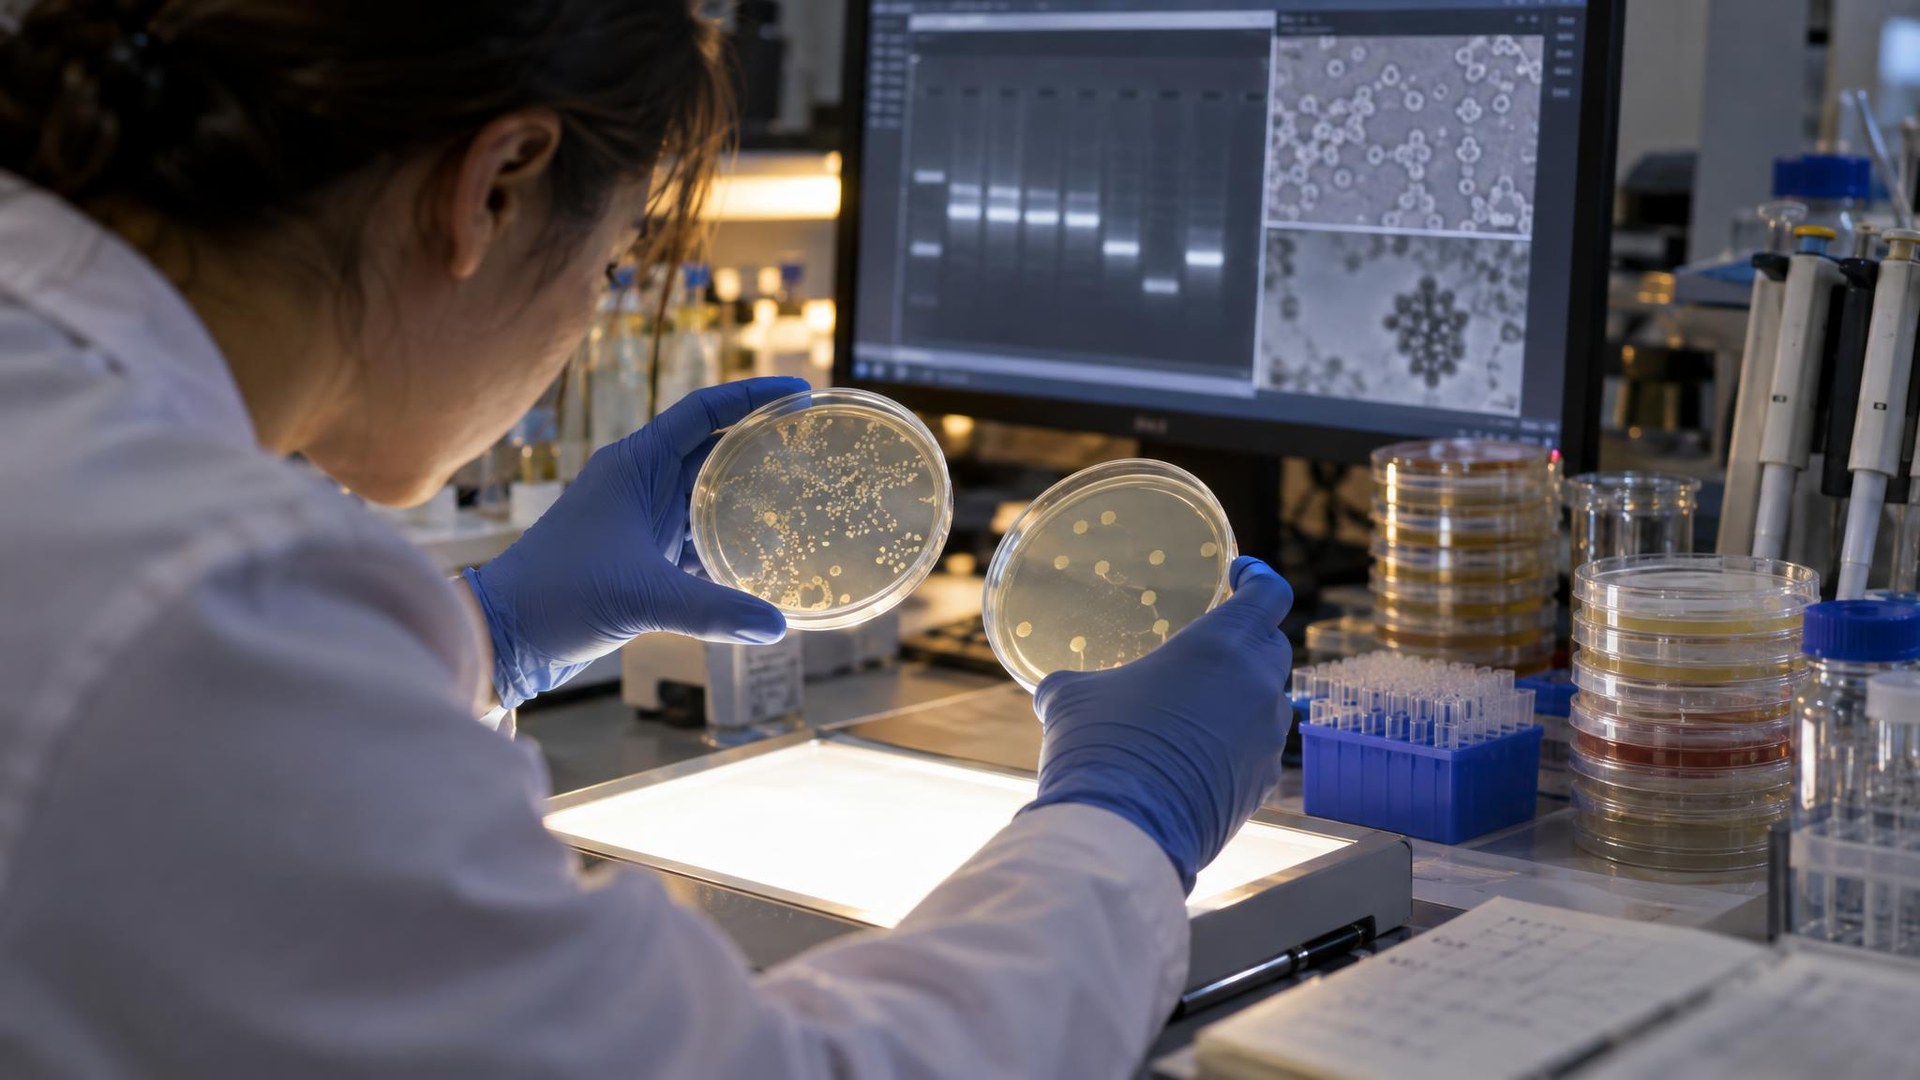
The tasks are built from data taken from real experiments, such as gel images, cell microscope photos, and colony culture dishes.
In some tasks, the AI noticed errors in the control group (the baseline experimental condition) and withheld its conclusions.
However, there were also mistakes, such as counting about 12% more colonies than the reference in colony counting, or choosing the wrong lane.
OpenAI warned that a higher score does not mean the results can be fully trusted in a lab.
Why it matters
If AI misreads experimental results, it could lead to using the wrong samples or drawing wrong conclusions, so benchmarks that check how reliable AI is in real labs are important.
Original article
OpenAI, AI 에이전트의 습식 실험실 데이터 해석 능력을 평가하는 BioBasicsBench 공개
Unite.AI · Nov 7, 2026, 7:18 AM GMT+9 · unite.ai
Read on Unite.AIAI read the original article and summarized it in plain language. It may contain mistakes, so please check the original for accuracy. The article's copyright belongs to Unite.AI.