
Suno opens Speech beta, a model that generates voice and music together
Source Suno blog
At a glance
Suno released Speech in beta, an audio model that creates spoken voice and background music together as one track. You enter an idea, a poem or your own writing, then describe the voice and musical style you want. After a month of testing with a small group, the beta is now open to everyone.
Key points
Suno describes Speech as the first audio model to produce speech and music in one combined track.
It is built right into Suno, so you only need to add your text and describe the voice and musical mood.
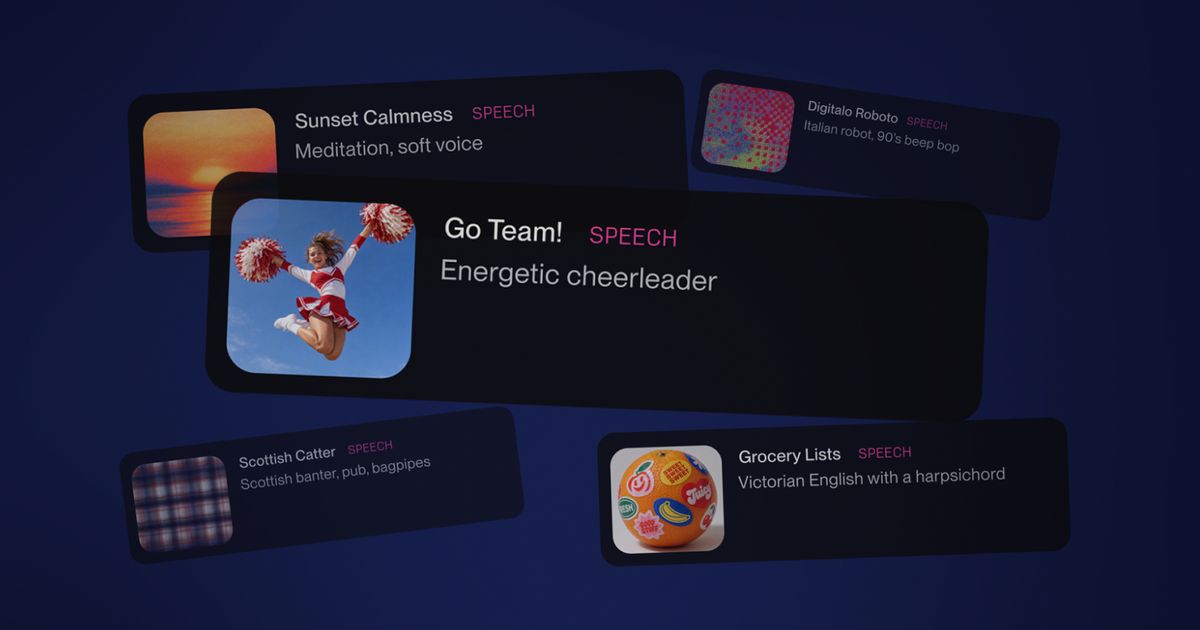
Suggested uses include meditations, poetry readings, pep talks and bedtime stories for kids.
As a beta it still has rough spots such as wandering accents, and Suno says it will keep improving it.
Why it matters
Beyond songs, Suno can now make spoken pieces like readings and stories, widening the range of personal works such as bedtime stories and pep talks.
Original article
Introducing Speech (beta)
Suno blog · Oct 2, 2026, 5:35 AM GMT+9 · suno.com
Read on Suno blogAI read the original article and summarized it in plain language. It may contain mistakes, so please check the original for accuracy. The article's copyright belongs to Suno blog.